See the SQL a pipeline compiles to
How-to · CohortDAG 0.2.9
Load the starter pipeline
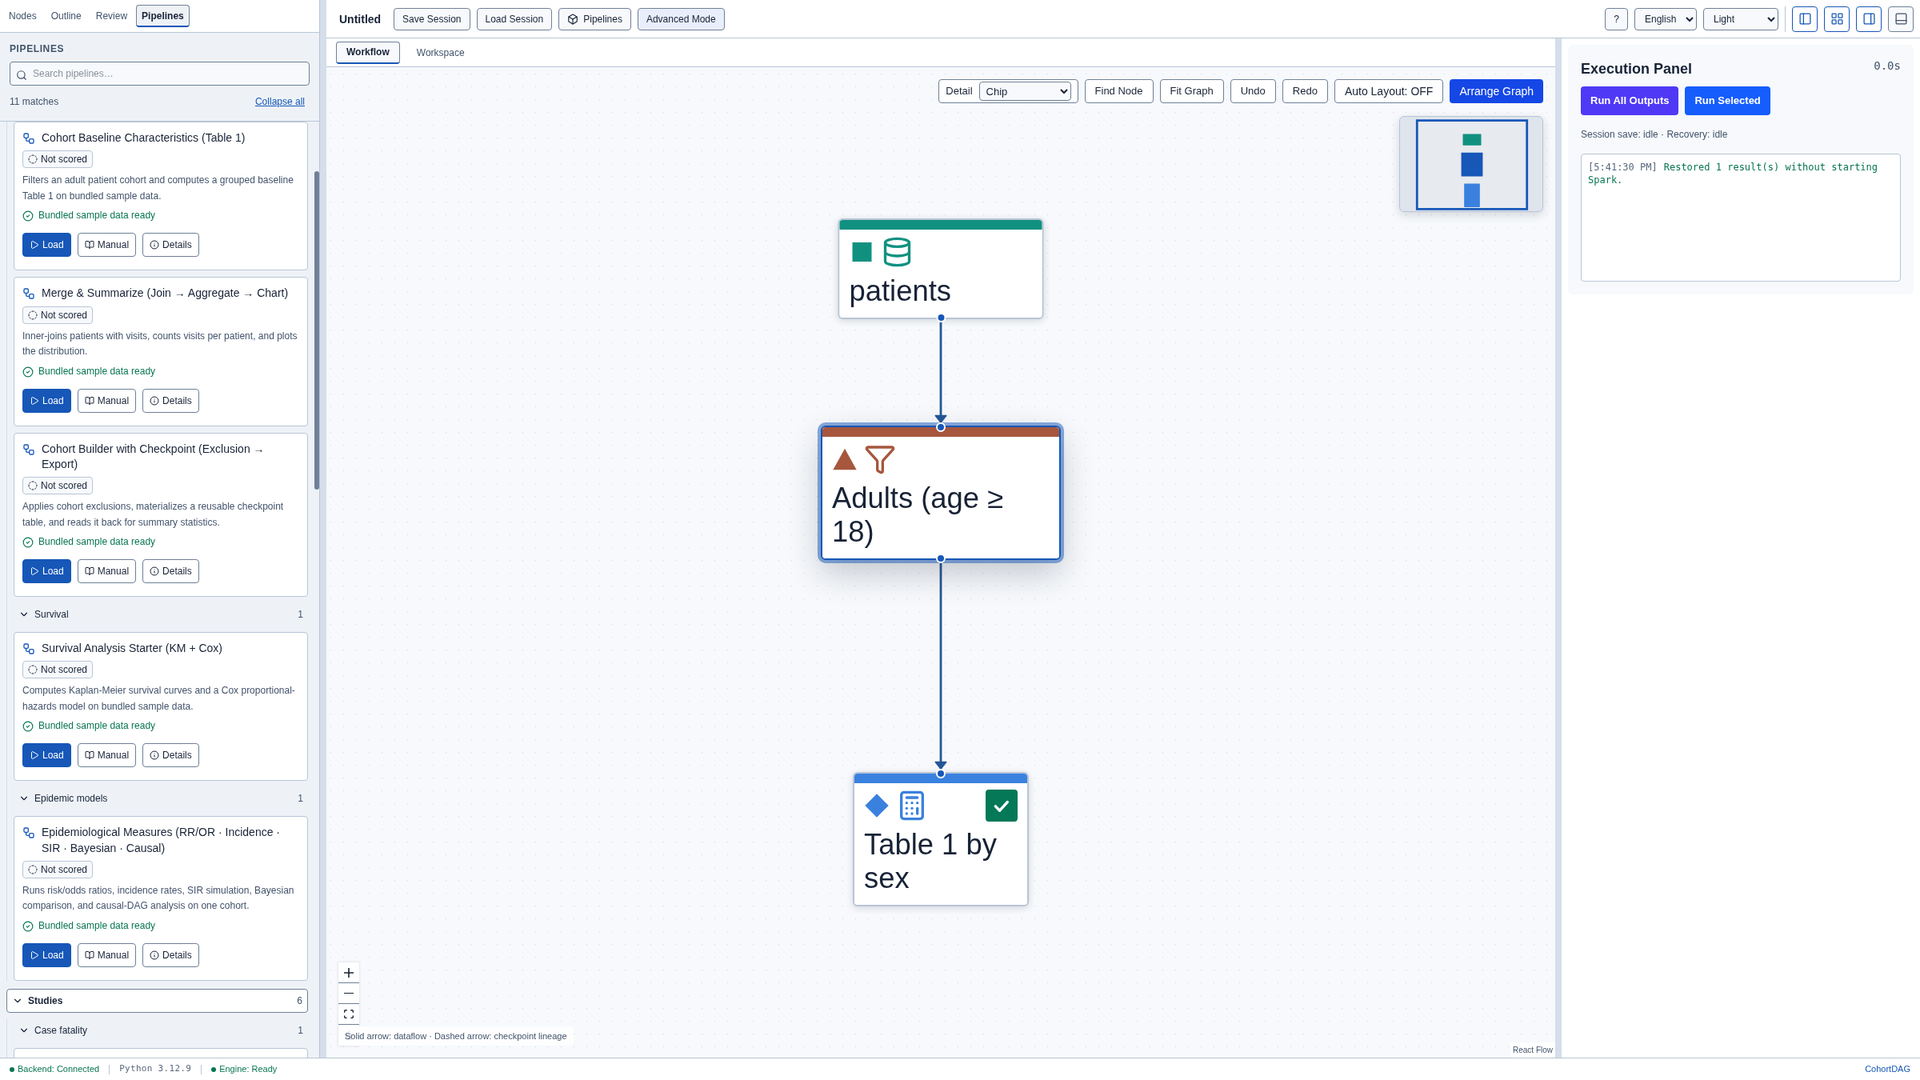
Click Pipelines and, under Starters, load Cohort Baseline Characteristics. It runs on sample data that ships with CohortDAG. Close the results panel and click Arrange Graph.
Turn on Advanced Mode
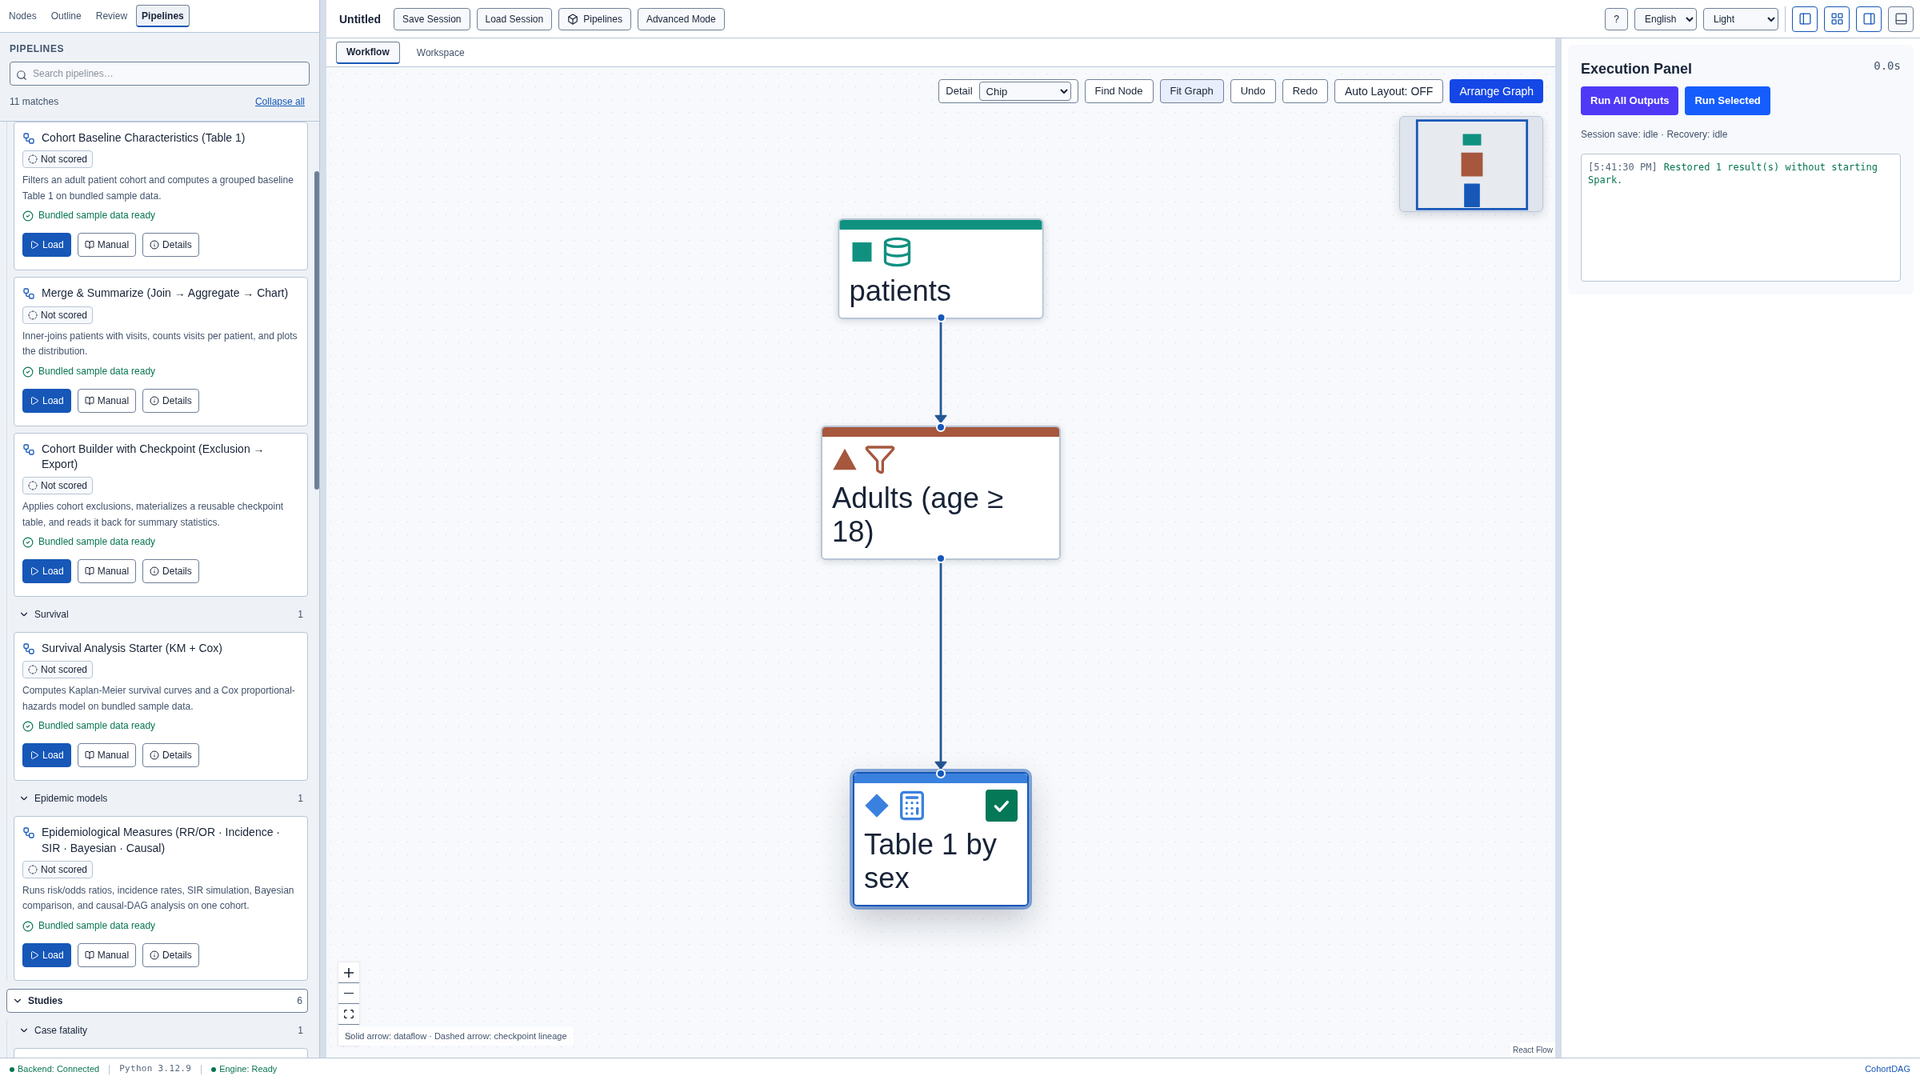
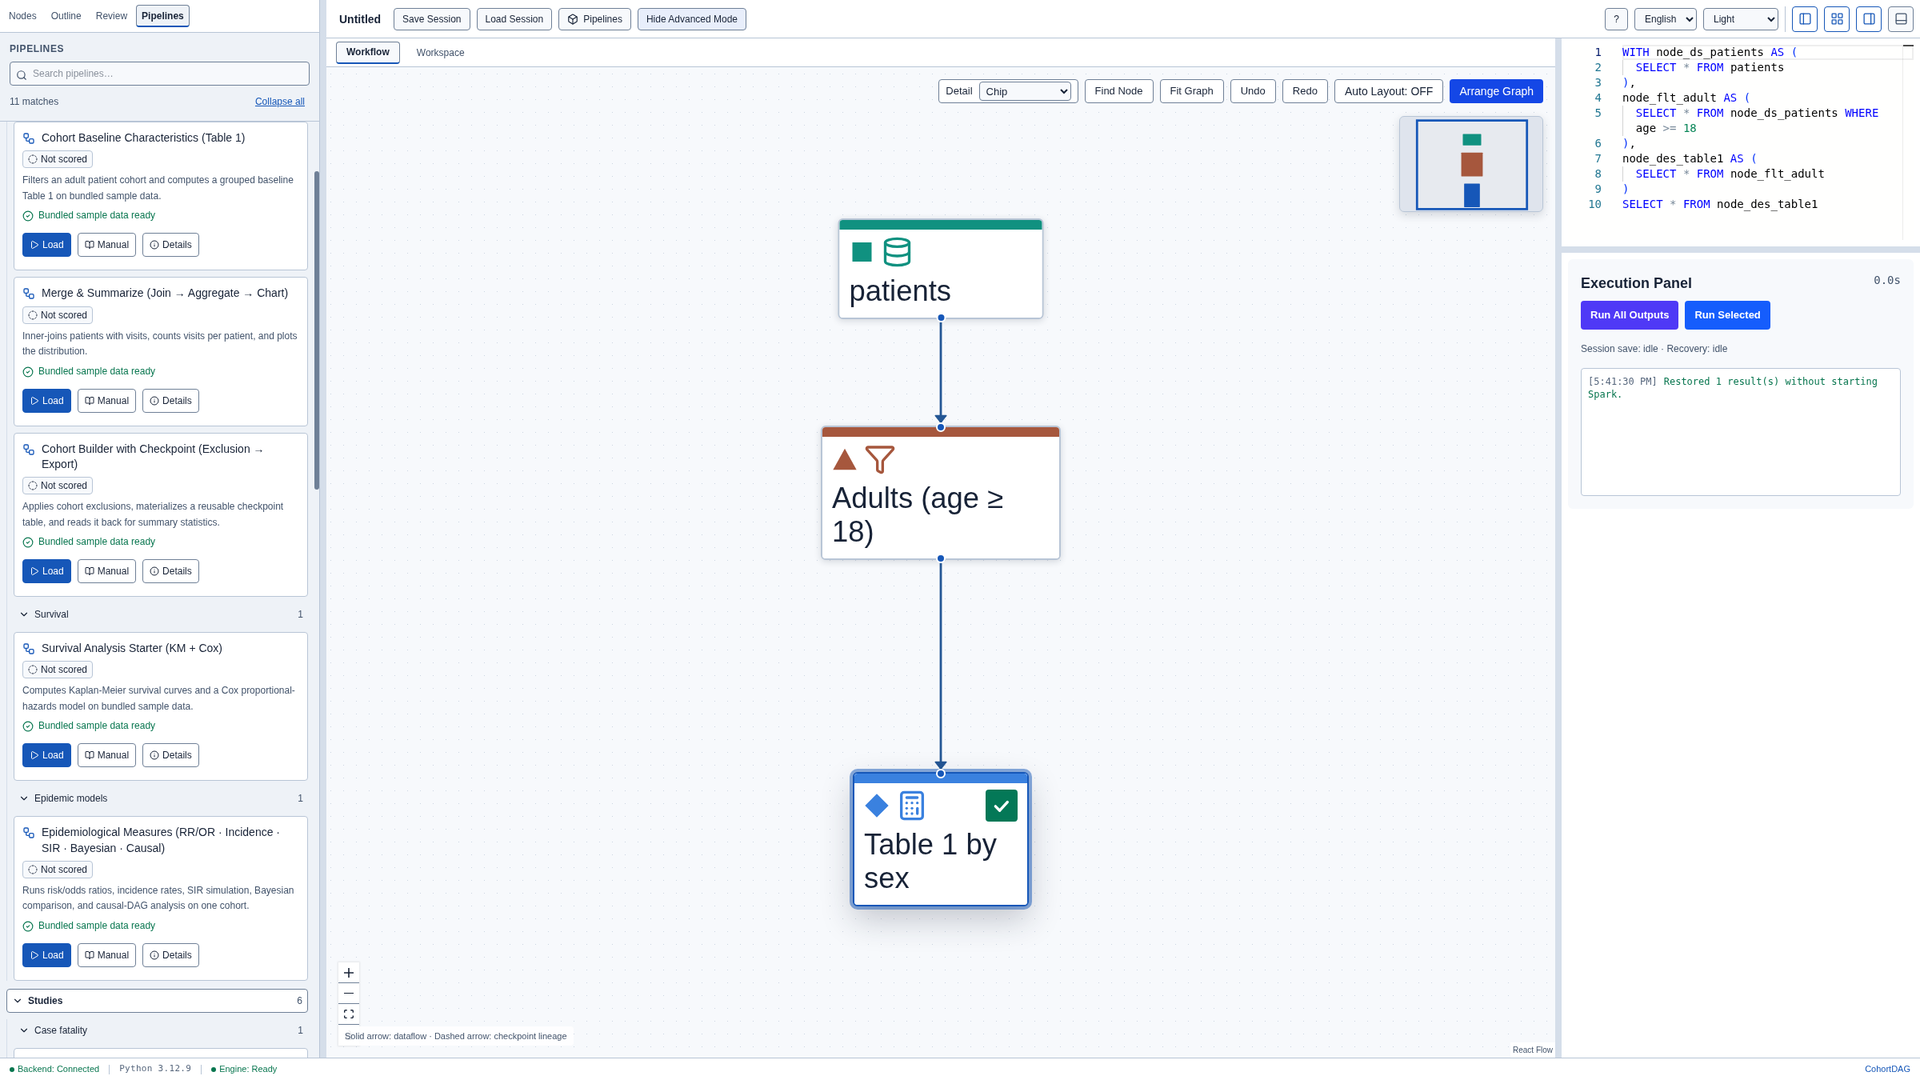
Click Advanced Mode. A read-only SQL panel opens above the Run panel on the right.
Read the compiled SQL
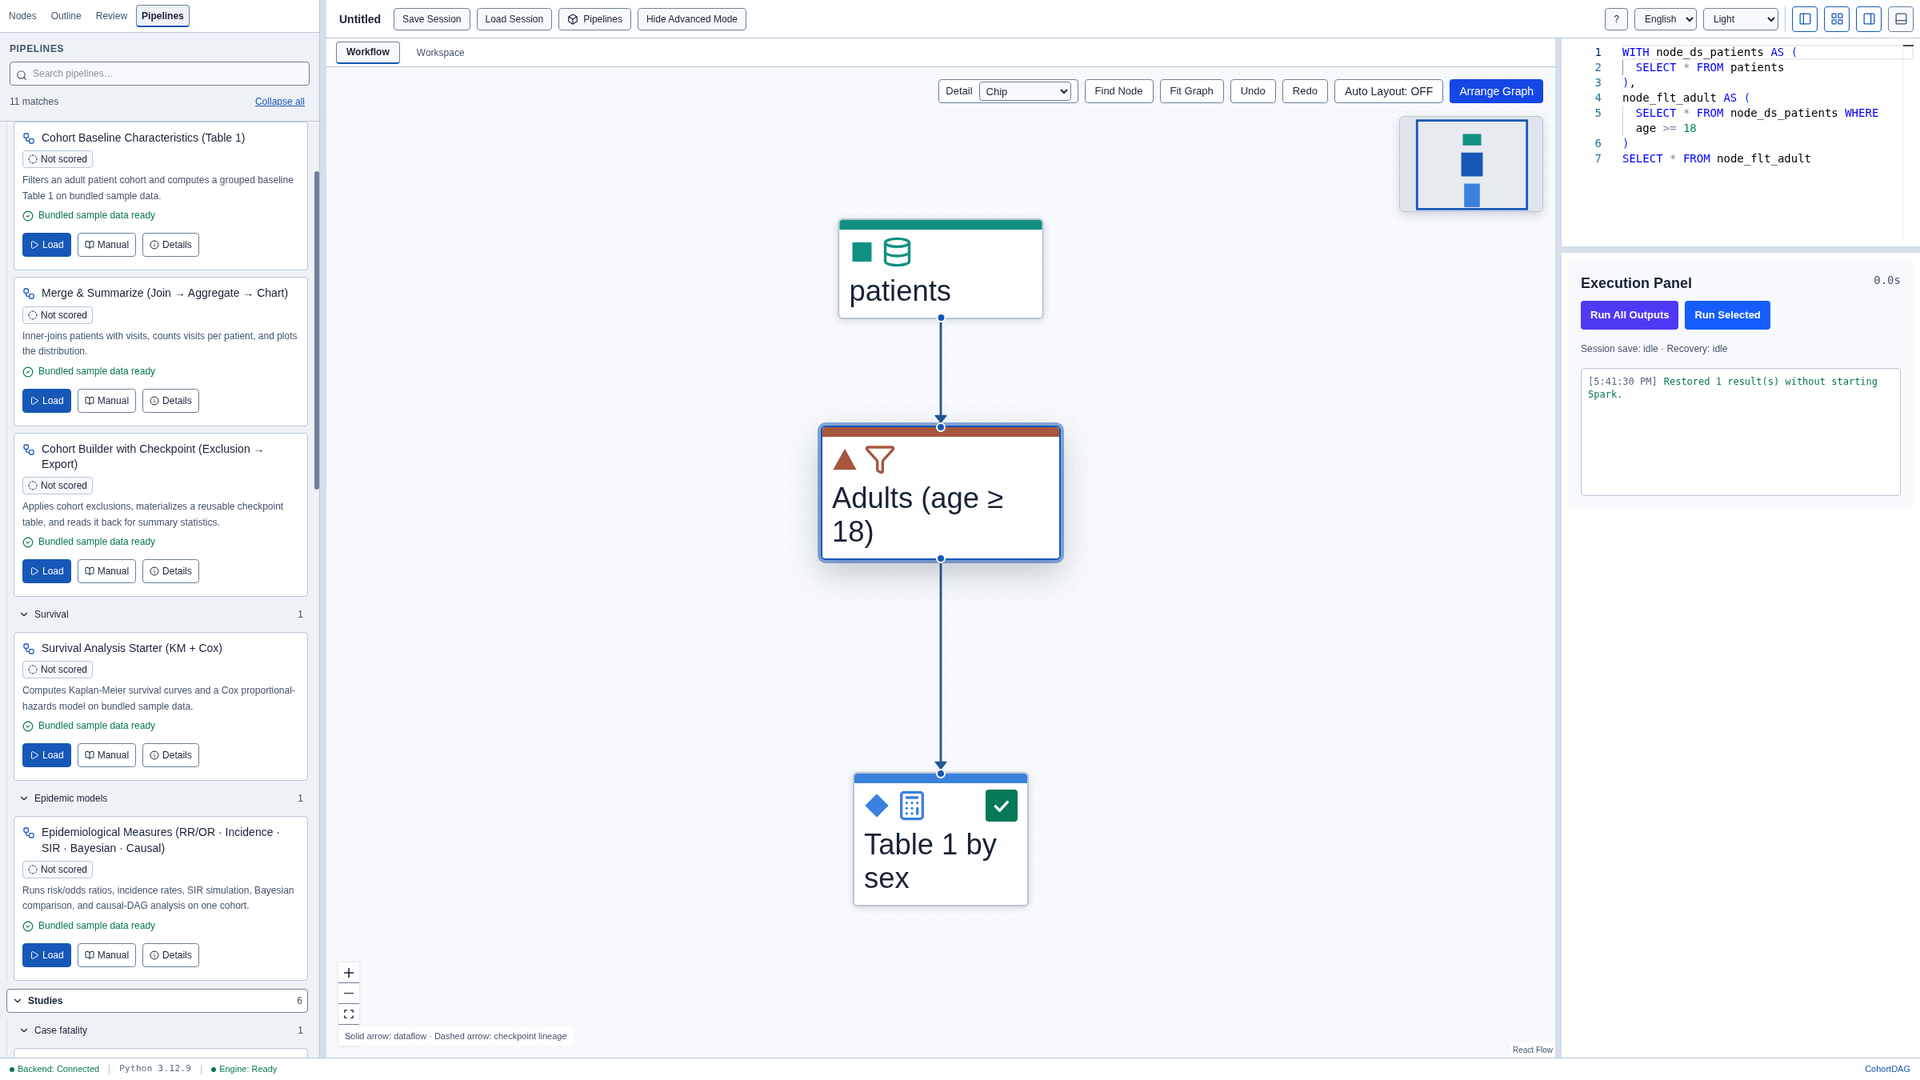
Select the Filter node. The panel shows the Spark SQL compiled for it, with a WHERE clause that keeps patients aged 18 or over.
Turn Advanced Mode off
Click Hide Advanced Mode to close the panel.